DeepSeek DeepInfer for production inference

Offline inference engine for DeepSeek-V4.1-Flash on SM100 and Ascend 950. Separate from deepseek-recipe protocols and the DeepSeek Harness agent runtime.

Three layers: DeepInfer, deepseek-recipe, DeepSeek Harness

DeepInfer, deepseek-recipe, and DeepSeek Harness solve different problems. Prefill and Decode are phases of the same engine.

Engine

DeepInfer

Production inference framework. Offline path for DeepSeek-V4.1-Flash.

  • SM100 · Ascend 950
  • Apache 2.0

Hardware details →

Protocols

deepseek-recipe

Request conversion, prompts, tokenization. Does not run inference.

  • pip install deepseek-recipe
  • MIT

Recipe guide →

DeepInfer vs deepseek-recipe vs DSH

LayerWhat it isInfers?LicenseStart
DeepInferOffline inference engine (V4.1-Flash)YesApache 2.0Install
deepseek-recipeProtocols / prompts / tokenizerNoMITRecipe
DeepSeek HarnessAgent runtimeN/ASee upstreamdshbase
Prefill / DecodeTwo phases of the same engineSame product—FAQ

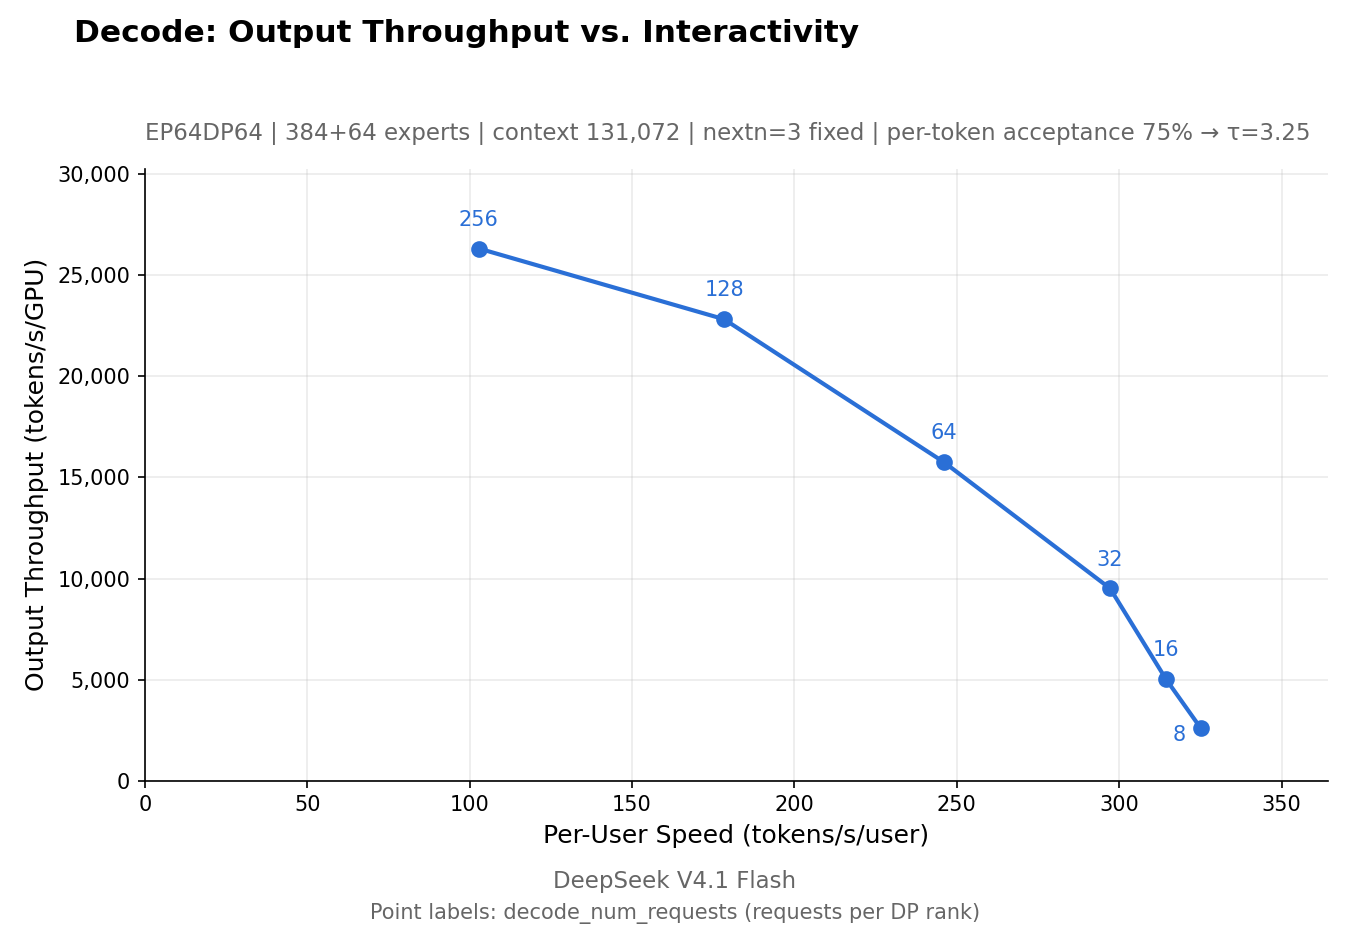
Official Prefill / Decode charts

From DeepInfer doc/images/. Production cluster figures (155T tokens/day, $38/GPU-hour, …) are not OSS install outcomes — see FAQ attribution and request pipeline.
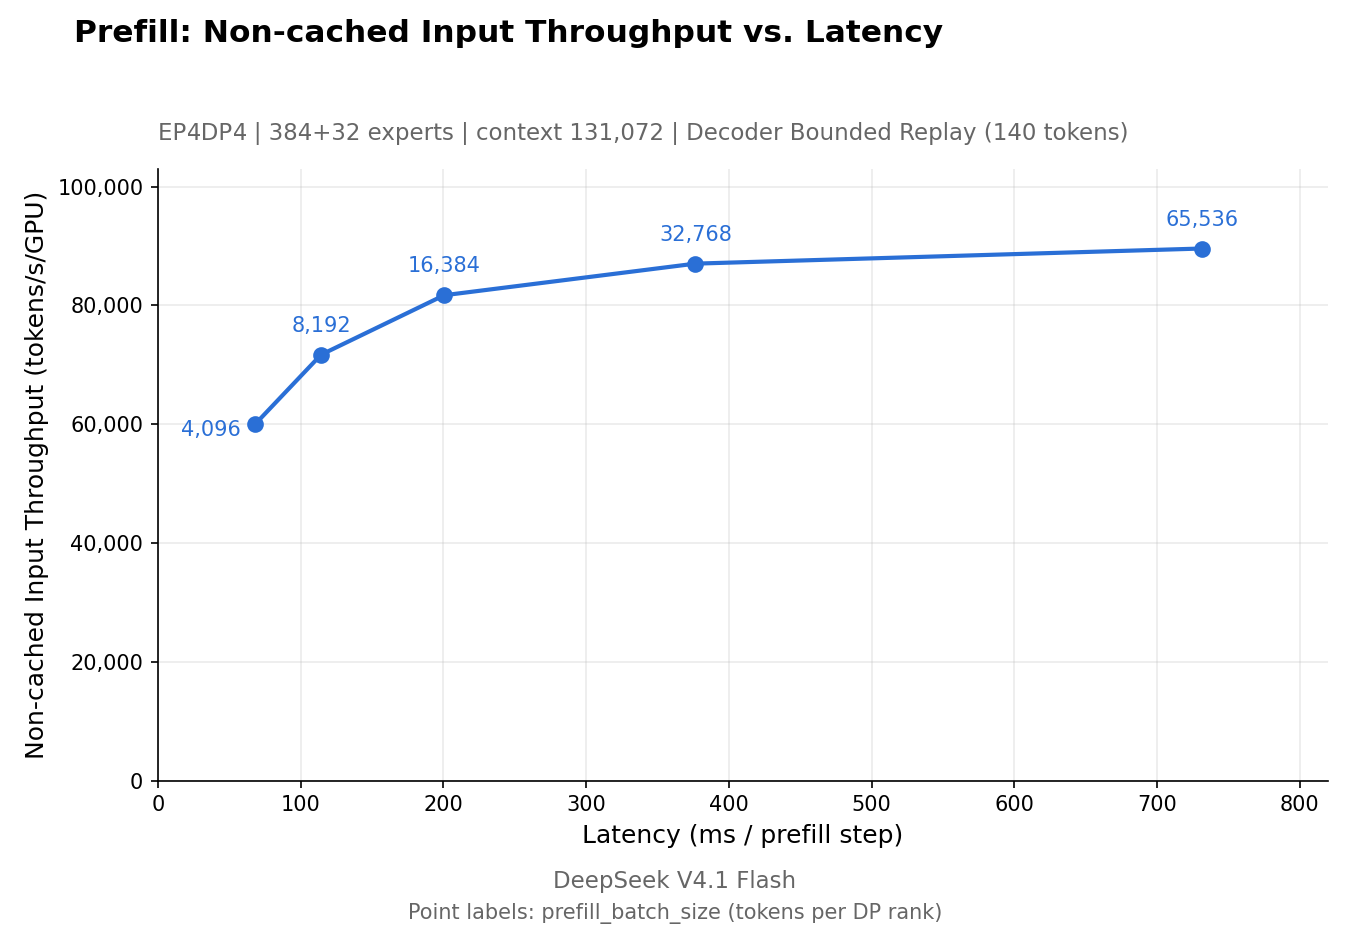
Prefill Pareto chart
Prefill Pareto · 4× SM100 topology (README)
Decode Pareto chart
Decode Pareto · 64× SM100 topology (README)

Who should skip — and who should install

See also the hardware gate.

Skip if you…

  • Only need the hosted DeepSeek API
  • Want an agent harness → DSH
  • Need protocols only → recipe
  • Don’t have SM100 or Ascend 950
  • Need full online serving (KV cache, PD disaggregation, DP LB — not in this release)

Install if you…

  • Run offline DeepSeek-V4.1-Flash
  • Have Linux, Python 3.12, GCC ≥ 13, CUDA 13 or CANN 9.2
  • Can follow the official README build

Open install guide